Umer Siddique

PhD Candidate, Department of Electrical and Computer Engineering, The University of Texas at San Antonio

Photo of Umer Siddique

I am a final-year PhD candidate in the Unmanned Systems Lab at UT San Antonio, advised by Prof. Yongcan Cao. My research is on AI alignment through reinforcement learning: building decision-making systems that are fair, safe, and aligned with the people they affect. I work on multi-objective and preference-based RL, multi-agent systems, and inference-time alignment, often using social welfare functions such as the Generalized Gini Function to balance efficiency and equity. My work is supported by the Office of Naval Research and the Army Research Laboratory.

Before UTSA, I received my MS from the UM–SJTU Joint Institute in Shanghai, where I worked with Prof. Paul Weng on fairness in reinforcement learning.
News

Oct 2026Paper on re-grounding frozen VLAs under actuation shift accepted at the CoRL 2026 Workshop on The Science of Physical AI Safety.
Sep 2026Interviewed by Texas Standard for The New Wild West: Texans on the AI Frontier.
Aug 2026Paper on rubric aggregation for multi-criterion LLM alignment accepted at the COLM 2026 Workshop on Agent Behavior.
2026Serving as a reviewer for ICML, NeurIPS, COLM, CoRL, AAAI, AAMAS, and TMLR in 2026.
May 2026Received the Gold Reviewer Award at ICML 2026.
May 2026Inference-Time Policy Alignment for Fair RL accepted at RLC 2026.
Apr 2026Multi-view media profiling suite accepted at ACL 2026.
Mar 2026Received the Jamshidi Fellowship from UT San Antonio.

All news →

Selected Publications

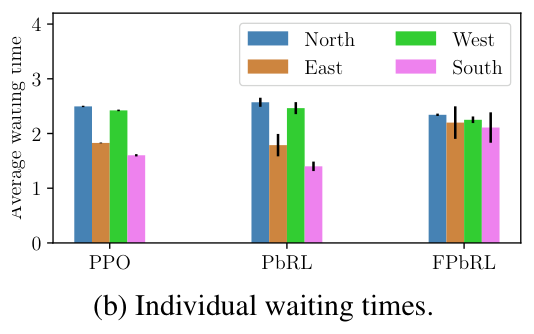
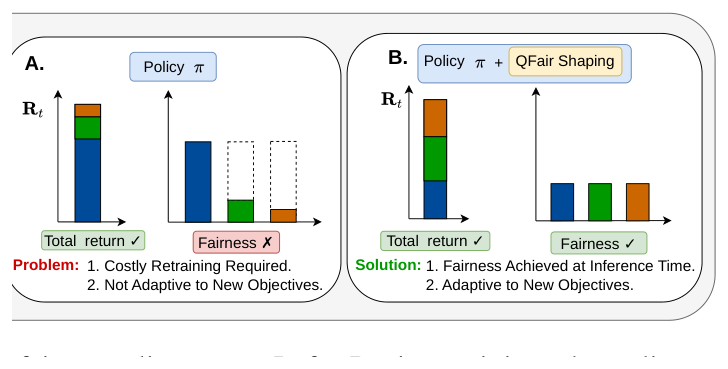
  1. RLC Figure from: Inference-Time Policy Alignment for Fair Reinforcement Learning
    Inference-Time Policy Alignment for Fair Reinforcement Learning
    Umer Siddique, Peilang Li, Conor Wallace and Yongcan Cao
    Reinforcement Learning Conference (RLC), 2026
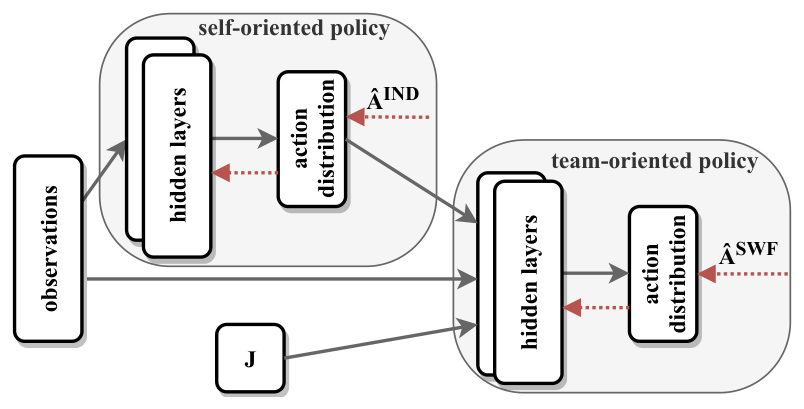
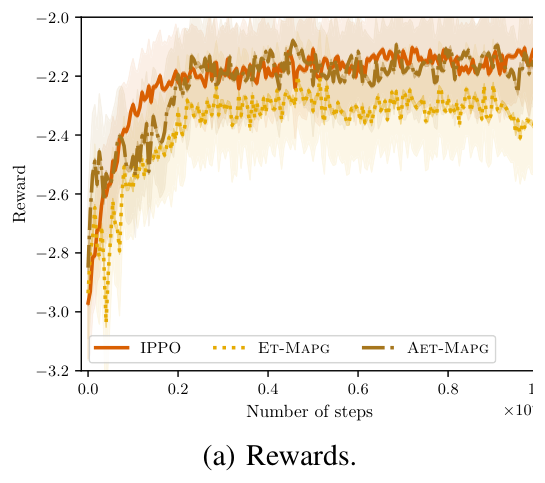
  2. ACC Figure from: Adaptive Event-Triggered Policy Gradient for Multi-Agent Reinforcement Learning
    Adaptive Event-Triggered Policy Gradient for Multi-Agent Reinforcement Learning
    Umer Siddique, Abhinav Sinha and Yongcan Cao
    American Control Conference (ACC), 2026
  3. MLJ Figure from: Learning Fair Policies in Multi-Objective Preference-based Reinforcement Learning
    Learning Fair Policies in Multi-Objective Preference-based Reinforcement Learning
    Umer Siddique, Abhinav Sinha and Yongcan Cao
    Machine Learning (Springer), 2025
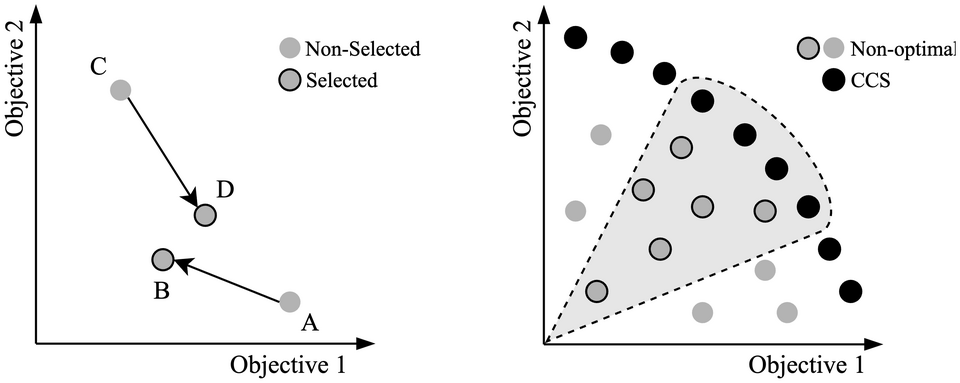
  4. RLC Figure from: Learning Fair Pareto-Optimal Policies in Multi-Objective Reinforcement Learning
    Learning Fair Pareto-Optimal Policies in Multi-Objective Reinforcement Learning
    Umer Siddique, Peilang Li and Yongcan Cao
    Reinforcement Learning Conference (RLC), 2025
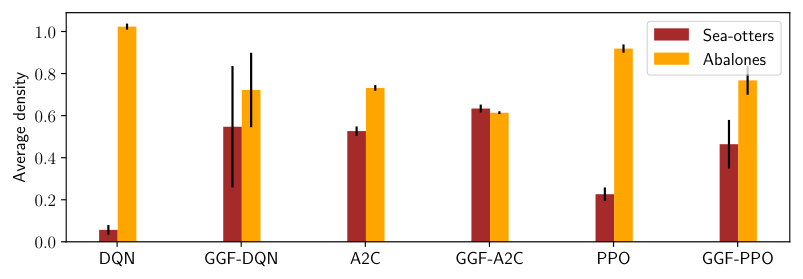
  5. ICML Figure from: Learning Fair Policies in Decentralized Cooperative Multi-Agent Reinforcement Learning
    Learning Fair Policies in Decentralized Cooperative Multi-Agent Reinforcement Learning
    Matthieu Zimmer, Claire Glanois, Umer Siddique and Paul Weng
    International Conference on Machine Learning (ICML), 2021
  6. ICML Figure from: Learning Fair Policies in Multi-Objective (Deep) Reinforcement Learning with Average and Discounted Rewards
    Learning Fair Policies in Multi-Objective (Deep) Reinforcement Learning with Average and Discounted Rewards
    Umer Siddique, Paul Weng and Matthieu Zimmer
    International Conference on Machine Learning (ICML), 2020

All publications →